ChatGPT citation rate benchmark: what good looks like
How to benchmark ChatGPT citation rate by prompt intent, target URL, competitor source share, and weekly page fixes instead of using one misleading AI visibility score.
ChatGPT citation rate looks simple until the team tries to use it as a benchmark. One run cites your site, another names you without a link, and a third sends the buyer to a competitor listicle. If you blend those outcomes into one "AI visibility" number, you lose the actual page fix.
The fast decision rule: benchmark ChatGPT citation rate by prompt intent and target URL, not as one sitewide average. A 12% citation rate on comparison prompts can be more valuable than a 55% citation rate on definitions because comparison prompts shape the shortlist.
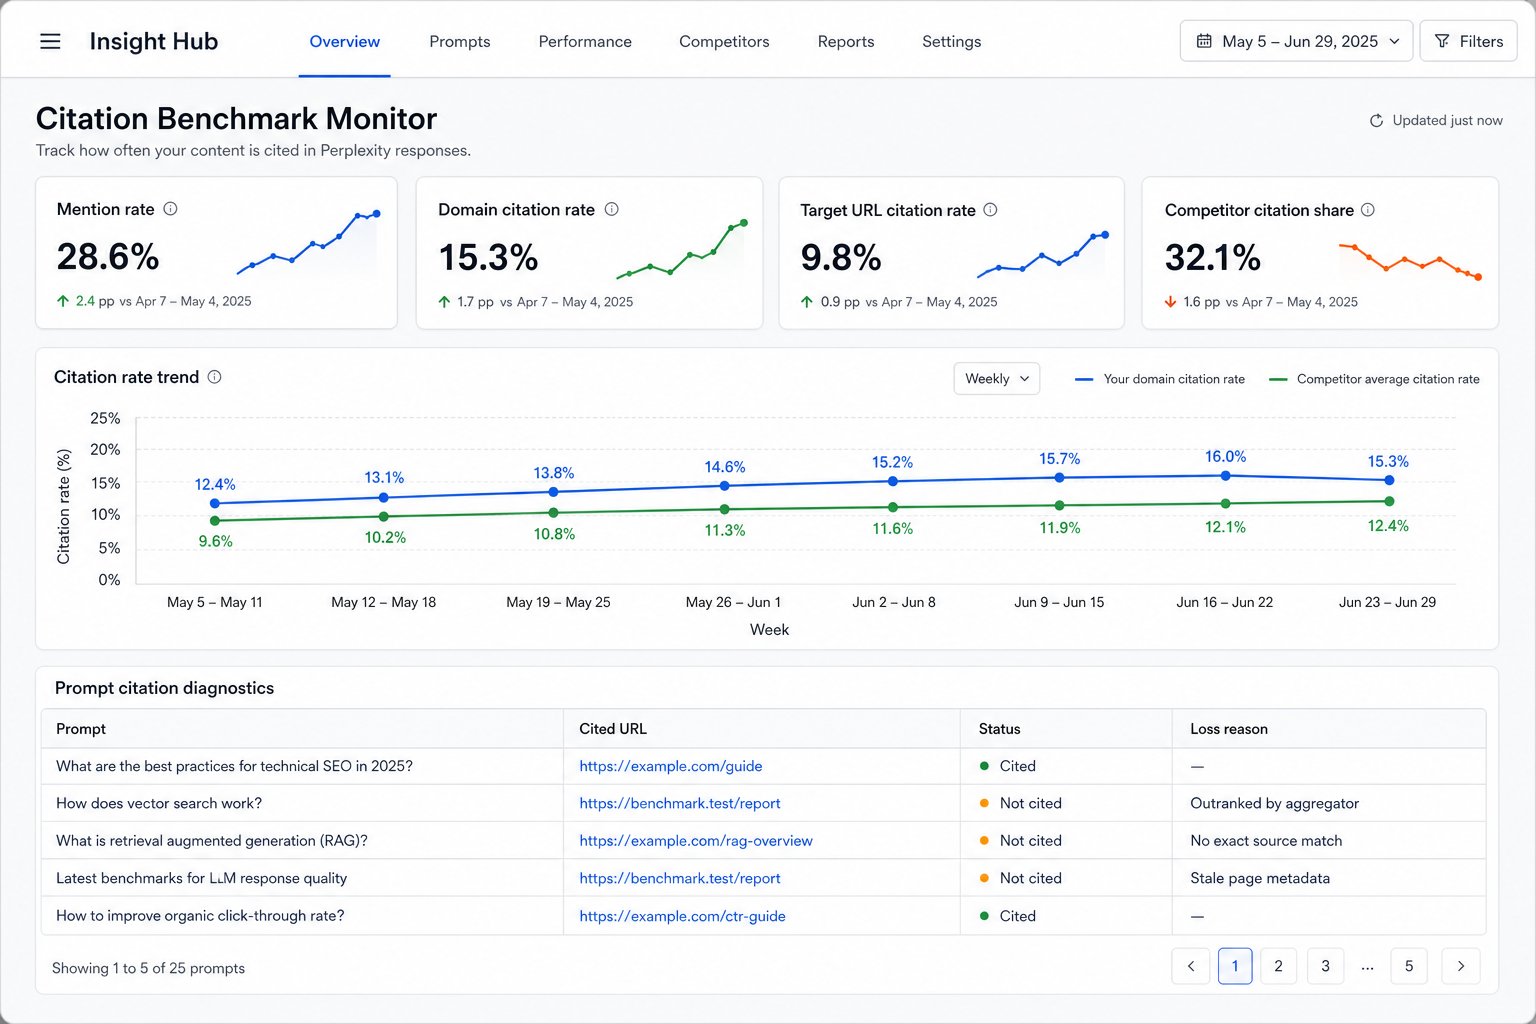
Use this after you understand ChatGPT citation tracking. If you still need the prompt set, start with ChatGPT SEO prompts. If you want the same logic for a more source-forward surface, compare it with the Perplexity citation rate benchmark.
What is a good ChatGPT citation rate?
A good ChatGPT citation rate is one that improves on the prompts where buyers need evidence, vendor comparisons, implementation advice, or proof before they act. Do not chase one universal benchmark. Track whether your domain is cited more often on high-intent prompts, whether the right page is cited, and whether competitor source share is falling.
ChatGPT citation rate is the percentage of tracked ChatGPT answers that cite your domain for a fixed prompt set. It should be reported separately from brand mention rate because ChatGPT can name a brand without giving the user a clickable source, and ChatGPT Search answers may include source links that users can inspect in the interface.
OpenAI's ChatGPT Search help page explains that search answers can include inline citations and source panels. For SEO teams, that makes citations measurable events: the answer either gave the buyer your URL, gave them a competitor URL, or gave them no source at all.
How do you calculate ChatGPT citation rate?
Calculate ChatGPT citation rate by dividing the number of prompt runs where ChatGPT cites your domain by the total number of relevant prompt runs. Then calculate target URL citation rate, which only counts answers that cite the page that should have owned the prompt.
Use this scorecard:
| Metric | Formula | What it tells you |
|---|---|---|
| Brand mention rate | Answers naming your brand / total prompt runs | Whether ChatGPT includes you in the answer |
| Domain citation rate | Answers citing your domain / total prompt runs | Whether your site owns source slots |
| Target URL citation rate | Answers citing the intended URL / total prompt runs | Whether the right page is being used |
| Owned citation share | Your cited URLs / all cited URLs in tracked answers | Whether competitors still control the source map |
| First-cited rate | Answers where your domain is the first cited source / citation-producing runs | Whether your source anchors the answer |
If you run each prompt three times, count runs rather than unique prompts. ChatGPT answers can vary because retrieval, answer framing, freshness, and source display vary between runs. A one-run "benchmark" is a screenshot, not a metric.
What benchmark should you use by prompt intent?
Use intent-weighted benchmark bands. Definition prompts usually produce cleaner citations, but they are not always the prompts that create pipeline. Comparison, alternatives, workflow, failure-mode, and pricing-adjacent prompts deserve more weight because they happen closer to a buying decision.
Start with these practical operating bands:
| Prompt intent | Example query | Early benchmark | Strong benchmark | Fix priority |
|---|---|---|---|---|
| Definition | "what is ChatGPT SEO" | 20-40% | 50-70% | Medium |
| Workflow | "how do I track ChatGPT citations every week" | 10-25% | 35-55% | High |
| Failure mode | "why does ChatGPT cite competitors instead of my site" | 5-20% | 30-50% | High |
| Comparison | "Tracemetry vs Profound for ChatGPT citation tracking" | 5-15% | 25-45% | Very high |
| Alternatives | "best Profound alternatives for AI visibility" | 5-15% | 25-45% | Very high |
| Pricing-adjacent | "which ChatGPT SEO tool is worth paying for" | 0-10% | 20-35% | Very high |
Treat these as operating bands, not public industry laws. A young site may start below them. A known publication, category leader, or review platform may exceed them. The useful question is whether the same locked prompt set improves after you ship page fixes.
Why is my ChatGPT citation rate lower than my mention rate?
Your ChatGPT citation rate is lower than your mention rate when ChatGPT recognizes the brand but does not use your site as the evidence source. That usually means your entity is known, but another page is clearer, fresher, more trusted, or a better match for the exact prompt.
Classify the gap before writing new content:
| Pattern | What it means | First fix |
|---|---|---|
| Brand named, competitor cited | You are considered, but competitor owns the proof | Improve the source page for that prompt |
| Brand named, publisher cited | Third-party proof is shaping the answer | Add source-worthy evidence and earn external mentions |
| Domain cited, wrong URL | Internal source mapping is unclear | Link the intended page from related cluster pages |
| Domain cited late | Your source supports a secondary claim | Add a stronger direct answer and table near the top |
| No citation, no mention | Retrieval or category clarity is weak | Create or rewrite the page that should match the prompt |
Google's structured data documentation frames markup as a way to help systems understand page content. Use that same discipline for ChatGPT citation work: schema can clarify a strong page, but the visible page still has to answer the prompt.
Which prompt set gives a reliable benchmark?
A reliable ChatGPT citation-rate benchmark uses a fixed prompt set across category discovery, ChatGPT-specific workflows, comparison, alternatives, failure-mode, and pricing-adjacent questions. The prompts should sound like buyer questions, not just keywords pasted into a tracker.
Use 40-80 prompts for the first benchmark:
| Bucket | Count | Example prompt |
|---|---|---|
| Category discovery | 8-12 | "what are the best AI visibility tools for B2B SaaS" |
| ChatGPT-specific | 6-10 | "how do I track ChatGPT citations for my brand" |
| Workflow | 6-10 | "how do I improve ChatGPT citation rate every week" |
| Comparison | 8-12 | "Tracemetry vs Profound for AI search monitoring" |
| Alternatives | 6-10 | "best Profound alternatives for startups" |
| Failure mode | 8-12 | "why does ChatGPT cite my competitors instead of my website" |
| Pricing-adjacent | 4-8 | "which AI visibility monitoring tool is worth paying for" |
Add entity terms naturally when they disambiguate the surface and use case: ChatGPT Search, OpenAI, citations, source links, cited URLs, brand mentions, citation rate, AI share of voice, AI visibility tracking, generative engine optimization, B2B SaaS, comparison pages, alternatives pages, FAQ schema, Article schema, and buyer shortlists.
How often should you re-measure the benchmark?
Re-measure ChatGPT citation rate weekly for active programs and monthly for passive monitoring. Weekly is fast enough to see movement after content updates, but slow enough to avoid reacting to every answer variation.
Keep the prompt wording, locale, surface, and sampling method stable. If you add new prompts, label them as a new cohort instead of blending them into the old baseline. Otherwise a reported "citation-rate lift" may only mean the team added easier prompts.
For each run, save:
- Prompt text and prompt bucket
- Date, country, and surface
- Brands named
- Cited domains and cited URLs
- Citation position
- Target URL expected
- Loss reason
- Page fix shipped
- Re-measurement date
That turns the benchmark into an action queue. Without the loss reason and next page fix, the report is just a scoreboard.
How do you improve a weak ChatGPT citation benchmark?
Improve the benchmark by fixing the highest-intent prompt where your domain is absent, the wrong URL is cited, or a competitor owns the source slot. Do not rewrite the whole site. Pick one source gap, make the intended page easier to retrieve, parse, trust, and cite, then re-measure the same prompt after the page is live.
Use this fix order:
- Pick the highest-weight loss. Comparison, alternatives, workflow, and pricing-adjacent prompts beat definitions.
- Inspect the cited competitor URL. Look at title, first answer block, tables, sources, FAQ, schema, update date, and internal links.
- Improve the intended page. Add a 40-80 word direct answer, a decision table, explicit entity language, and source-backed claims.
- Clarify internal links. Link from ChatGPT SEO, ChatGPT citation tracking, content that AI cites, and schema markup for AI search.
- Align FAQ and schema. The FAQ answers in schema should match visible page text.
- Re-measure after 7-14 days. Track target URL citation rate, not only domain citation rate.
If ChatGPT cites a publisher, directory, Reddit thread, or review site instead of any vendor page, the fix may include earned proof. Your page can be well structured and still lose when the answer needs third-party validation.
What should a weekly citation-rate report show?
A weekly ChatGPT citation-rate report should show the score, the prompts behind the score, the competitor URLs winning source slots, the page fixes shipped, and whether prior fixes changed the next run. The report should end with one concrete content or proof action.
Use this compact report format:
| Section | What to include |
|---|---|
| Executive score | Mention rate, domain citation rate, target URL citation rate, owned citation share |
| High-intent movement | Comparison, alternatives, failure-mode, workflow, and pricing-adjacent changes |
| Competitor source wins | Domains and URLs cited instead of yours |
| Recovered prompts | Prompts that moved from absent to mentioned or cited |
| Page fixes shipped | URLs updated, internal links added, schema changed, sources added |
| Next action | One page or proof gap to fix this week |
For a first baseline, run the free Tracemetry audit. For weekly tracking, Tracemetry Pro keeps the prompt set stable, separates mentions from citations, turns losses into source-grounded briefs, and shows whether citation ownership improves after each fix. When the benchmark shows that a competitor owns the source slot, use the ChatGPT competitor citation workflow to diagnose the gap before rewriting pages.
Start with the benchmark, then fix one source gap
Do not ask "what is our ChatGPT visibility?" as one giant question. Ask which prompts mention you, which prompts cite you, which URL was cited, which competitor owns the source slot, and which one page fix would change next week's score.
That is the difference between a vanity AI visibility chart and a useful ChatGPT citation-rate benchmark. The chart says whether you are present. The benchmark tells you what to fix next.
For the surrounding workflow, read ChatGPT citation tracking, use the ChatGPT SEO prompts starter set, and then run the free audit to find the first source gap worth fixing.
FAQ
What is ChatGPT citation rate? ChatGPT citation rate is the percentage of tracked ChatGPT prompt runs where the answer cites your domain. It should be measured separately from brand mention rate because ChatGPT can name a brand without linking to the brand's website.
What is a good ChatGPT citation rate? A good ChatGPT citation rate is one that improves on high-intent prompts over time. For early programs, compare definition, workflow, comparison, alternatives, failure-mode, and pricing-adjacent prompts separately instead of using one blended benchmark.
How many prompts do I need for a ChatGPT citation benchmark? Use 40-80 prompts for a stable early benchmark. Run the most important prompts multiple times, keep wording stable, and separate new prompt cohorts from the original baseline.
Why does ChatGPT mention my brand but cite a competitor? That usually means ChatGPT recognizes your brand but finds a competitor, publisher, review site, or community page to be a clearer evidence source for the specific prompt. Improve the intended page and add third-party proof where needed.
Should I track target URL citation rate? Yes. Domain citation rate tells you whether your site appeared. Target URL citation rate tells you whether the correct page owned the prompt. The second metric is better for deciding what to fix.
Frequently asked questions
What is ChatGPT citation rate?
ChatGPT citation rate is the percentage of tracked ChatGPT prompt runs where the answer cites your domain. It should be measured separately from brand mention rate because ChatGPT can name a brand without linking to the brand's website.
What is a good ChatGPT citation rate?
A good ChatGPT citation rate is one that improves on high-intent prompts over time. For early programs, compare definition, workflow, comparison, alternatives, failure-mode, and pricing-adjacent prompts separately instead of using one blended benchmark.
How many prompts do I need for a ChatGPT citation benchmark?
Use 40-80 prompts for a stable early benchmark. Run the most important prompts multiple times, keep wording stable, and separate new prompt cohorts from the original baseline.
Why does ChatGPT mention my brand but cite a competitor?
That usually means ChatGPT recognizes your brand but finds a competitor, publisher, review site, or community page to be a clearer evidence source for the specific prompt. Improve the intended page and add third-party proof where needed.
Should I track target URL citation rate?
Yes. Domain citation rate tells you whether your site appeared. Target URL citation rate tells you whether the correct page owned the prompt. The second metric is better for deciding what to fix.
Make your next SEO decision with better evidence.
Explore practical guides to AI visibility, source citations, and choosing the right tools for your team.